Language Technologies Lab
Language Technologies Lab
Research
Publications
Projects
Tools
People
News
Work with us
Prompting
Rationalization via LLMs
Evaluate whether large language models can perform selective rationalization through prompting.
Mar 2, 2026
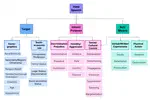
Untangling Hate Speech Definitions: A Semantic Componential Analysis Across Cultures and Domains
HateDefCon breaks 493 hate speech definitions from five domains into semantic components and shows LLM hate speech detection changes with the definition in the prompt.
Katerina Korre
,
Arianna Muti
,
Federico Ruggeri
,
Alberto Barrón-Cedeño
Cite
DOI
URL
Is It Worth Using LLMs for Unfair Clause Detection in Terms of Service?
Seven large language models, prompted in three ways, face fine-tuned classifiers at spotting unfair clauses in Terms of Service, and the fine-tuned classifiers still win.
Marco Panarelli
,
Andrea Galassi
,
Francesca Lagioia
,
Rūta Liepiņa
,
Marco Lippi
,
Przemysław Pałka
,
Giovanni Sartor
PDF
Cite
DOI
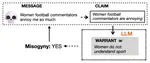
Language is Scary when Over-Analyzed: Unpacking Implied Misogynistic Reasoning with Argumentation Theory-Driven Prompts
Prompting LLMs to rebuild the hidden reasoning of implicit misogyny shows that they often reach the right label for the wrong reasons.
Arianna Muti
,
Federico Ruggeri
,
Khalid Al Khatib
,
Alberto Barrón-Cedeño
,
Tommaso Caselli
Cite
DOI
URL
Cite
×